The Decision Subtraction Framework: How to Evaluate Any AI Tool
The Durability CurveLast week someone asked me which AI tools they should be using. The question sounded simple. But it hides a problem that costs people real money and real time.There are more capable AI tools available today than any single person can evaluate. ChatGPT Plus at $20/month. Claude at $20. Grok at $30. Cursor at $20. Copilot at $10. Those are just the headline tiers. Each has a $100, $200, or $300 variant underneath. Each claims to be the one that earns its place.The real question is not which tool is best. The real question is: which tools subtract more decisions than they add?That single question separates tools that compound your capability from tools that compound your cognitive load.Here is a framework to answer it in 10 minutes.
Subscribe to The Durability Curve on Substack — free weekly analysis on AI infrastructure, verification, and durable systems.
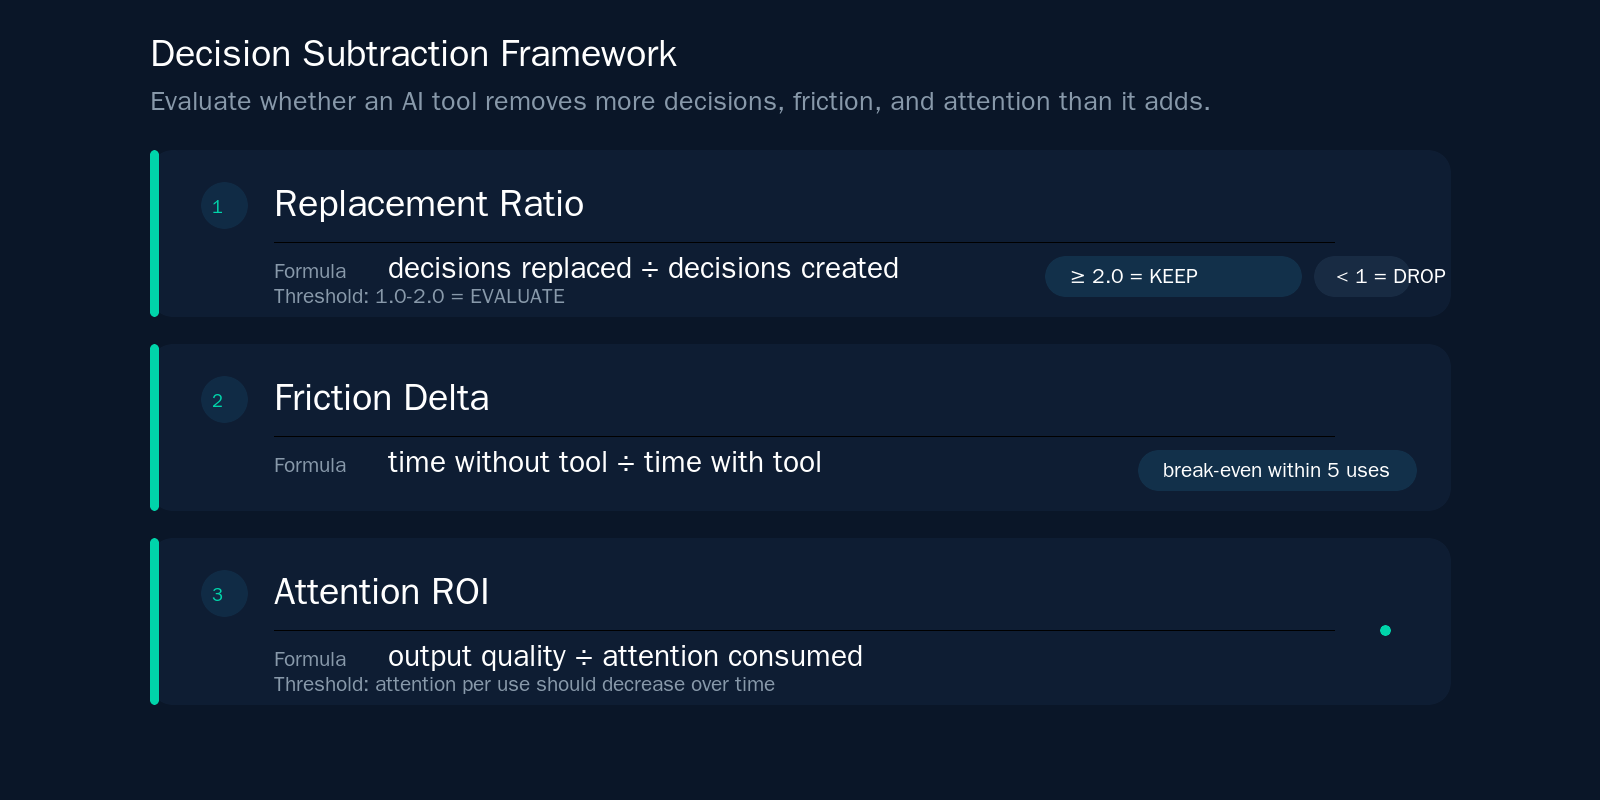
The Three Lenses
Every AI tool changes your relationship with decisions. It either replaces decisions you used to make, or creates new ones you did not have before. The ratio between these two determines whether the tool earns its place or drains your attention.
Lens 1: Replacement Ratio
The formula: decisions the tool replaces ÷ decisions the tool creates.
How to calculate it:List every decision the tool makes for you. Then list every decision it forces you to make that you would not have had otherwise. Divide the first number by the second.
The thresholds:Ratio ≥ 2.0 → keep. 1.0 – 2.0 → evaluate. < 1.0 → drop.
Example:A code completion tool that writes a function body (replaces 5 decisions about syntax, structure, variable naming) but forces you to review the output (adds 2 decisions about correctness and style) has a ratio of 2.5. It passes.A meeting summariser that condenses an hour of discussion (replaces 1 decision: should I re-listen to this?) but requires you to verify accuracy, add context, and decide what to share (adds 3 decisions) has a ratio of 0.33. It fails.
Lens 2: Friction Delta
The formula: time required to do the task without the tool ÷ time required with the tool.
How to calculate it:Include the onboarding time amortised over your first 10 uses. A tool that saves 30 minutes per use but took 2 hours to learn breaks even at 4 uses. After that, it is pure gain.
The threshold:Break-even within 5 uses. If the tool has not paid back its learning cost by then, the friction is too high.
The catch:This lens breaks for tools that enable tasks you could not do at all before. A drug discovery simulation has infinite Friction Delta because the alternative is not slower - it is impossible. Score those as "can't evaluate on this lens" and rely on the others.
Lens 3: Attention ROI
The formula: quality of output ÷ attention units consumed.
How to calculate it:Estimate the cognitive load per use on a simple scale: 1 (fire and forget), 2 (check the output), 3 (monitor and correct), 4 (full attention required). Track whether this number goes up or down over 10 uses.
The threshold:The tool should require less attention per use over time, not more. If you need to watch it more closely after ten uses than after one, something is wrong - either the tool is not learning your patterns, or its outputs are degrading.
Where This Framework Lies to You
I tested this framework against the hardest cases I could find. It failed in five ways. Knowing them makes the framework useful. Not knowing them makes it dangerous.
1. Decision quality matters more than quantity
Replacing 10 trivial choices with 1 strategic judgment that surfaces a hidden risk has a ratio of 0.1. The framework says drop it. That is a bad call. The replacement ratio needs a weighting: a decision about whether to deploy to production carries more consequence than 10 decisions about should I use camelCase here. If a tool replaces one high-stakes decision, treat that decision as worth 5–10 ordinary ones.
2. Friction Delta cannot measure capability expansion
A tool that lets you analyse a dataset you could not touch before has infinite “time without” - you could not do the task at all. The formula divides by infinity and returns nothing useful. The fix: if a tool enables something new rather than speeding up something old, skip the Friction Delta test and weight the other two lenses more heavily.
3. Attention ROI rewards deskilling
The descending attention threshold has a hidden trap. A tool that trains you to skim, to pattern-match, to rubber-stamp its output will show beautifully decreasing attention scores. You will trust it more while understanding less. The vault calls this specification gaming - the metric becomes the target, and the target degrades the capacity it was meant to measure.
4. The erasure cost is invisible
The framework only measures present efficiency. It never asks: “If I use this for a year, what can I no longer do without it?” A tool that automates your email triage may save 20 minutes a day for the first year, but if your inbox management skill atrophies, switching to a different tool becomes impossible without a painful relearning period. This is erasure cost - the hidden debt of tool dependency.
5. Error asymmetry is invisible
Two tools can score identically on all three lenses while producing catastrophically different outcomes when they fail. A hallucinating chatbot and a calibrated-but-slower reasoning engine will look similar on paper. The difference is what happens when they are wrong. Always test a tool’s failure mode before subscribing - not its success mode.
The Fourth Lens: Erasure Cost
Add this check to every evaluation:
Ask: “If I use this tool for six months and then stop, what skill or knowledge will I have lost?”
Score it: 1 (nothing lost - pure augmentation), 2 (some context lost, recoverable in a week), 3 (significant atrophied skill, hard to recover), 4 (core competency outsourced, cannot function without it).
Threshold: Score 1–2 is safe. Score 3 requires a deliberate choice - you are trading skill for speed, which may be worth it. Score 4 is dependency, not tooling.
How to Apply: Monday Morning
Set aside 30 minutes. Here is what to do:
Step 1. List every AI tool you have used in the last 30 days. Include the free trials, the ones you forgot about, the ones embedded in other products (Copilot in VS Code, AI features in Notion, whatever your CRM shipped last quarter).
Step 2. For each one, score Replacement Ratio and Friction Delta. Be honest about the decisions the tool creates - the checking, the verifying, the fixing, the context-switching back to tell it what you actually meant.
Step 3. Apply the thresholds: both pass → keep. One fails → 7-day trial with explicit measurement. Both fail → cancel.
Step 4. Score Erasure Cost for the survivors. If a tool scores 4, ask whether the speed gain justifies the dependency.
Step 5. When evaluating a new tool: score it before subscribing. If it would not pass on paper, do not install it. The thirty-second install is a trap. The ten-minute evaluation is the real gate.
Worked Examples
Here is how three common tools score through the framework. Prices are as of May 2026.
ChatGPT Plus ($20/month)
- Replacement Ratio: 3.5. Replaces research lookups, drafting, formatting decisions. Creates verification and prompt decisions. Pass.
- Friction Delta: Breakeven in 2-3 uses. Shallow learning curve. Pass.
- Attention ROI: Decreasing - gets faster as you learn its patterns. Pass.
- Erasure Cost: 2. You may rely on it for first drafts, but the underlying skill is reinforced, not replaced.
- Verdict: Keep. Justifies its price.
Cursor Pro ($20/month)
- Replacement Ratio: 4.0. Replaces syntax lookups, boilerplate, function structure. Creates code review decisions. Pass.
- Friction Delta: Breakeven in 1-2 uses. Tab completion is instant. Pass.
- Attention ROI: Steeply decreasing - the model learns your coding patterns. Pass.
- Erasure Cost: 3. Heavy users report difficulty writing syntax without it after 3+ months. A deliberate trade worth making for professional developers.
- Verdict: Keep for daily coding. Monitor erasure.
Meeting Summariser ($20/month, anonymised)
- Replacement Ratio: 0.33. Replaces 1 decision (should I re-listen?). Creates 3 decisions (verification, context, sharing). Fails.
- Friction Delta: Never breaks even - you still attend the meeting, and the summary needs verification. Fails.
- Attention ROI: Flat - you must check every summary at the same attention level. Fails.
- Erasure Cost: 2. You still attend meetings. Minor skill atrophy.
- Verdict: Cancel. The tool creates more overhead than it removes.
Why This Works
The framework is static. The market moves every week. Subscribe to The Durability Curve on Substack for the live overlay - which companies, which signals, which falsifiers are triggering this quarter.