Supervised Learning
Ibragimov FakhriddinSupervised Learning is extremely common and intuitively understandable. The idea is simple - we have some data, so let's use it to train the model to predict particular variable (called "target variable") based on these data. Data we use to train must be in pair form of (feature, target value) - so called "training set". After training, model will take only features, as an input, and give target variable's value, as an output.
But how can we be sure that this model is actually working and not giving some random values ? To handle it, we take small portion of data, which will not be included in training set, and test our model on it, such set is called "test set".
What is model actually ? Model is just a function with dependent (constants) and independent (features) variables, which outputting prediction. The simplest one is :
h(x) = x*k + b
Here h means hypothesis (model's prediction), x is feature and k & b constants are called weights. By changing these weights we change the prediction trying to make it as close to true value as possible.
What about measurement of error ? How to understand is it good model or not ? In order to empirically estimate its work, loss functions are used. It is just a function which takes prediction and true value, and output number, which is called error. The simplest one is just :
f(true_value, prediction) = prediction - true_value
It is very rough and not used in practice. Instead, pretty popular is :
f(true_value, prediction) = (prediction - true_value)^2
It has 2 key benefits :
1) Output is only positive
2) If our prediction is pretty decent, loss function's output is low, like : (0.05)^2 = 0.0025. And vice versa, when prediction is far from true value, function is outputting huge numbers, like : (25)^2 = 625.
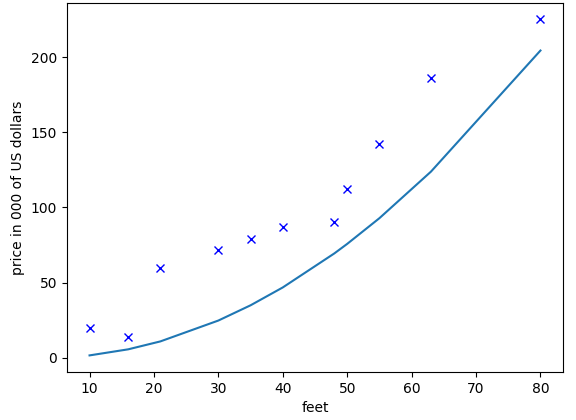
If we want predictions to be continuous, it means we are trying to solve regression problem. Notoriously known example : predict house price based on its area (in square feet).
However, if you want predictions to be finite, like : answer to question is it human or not (0 or 1), it means we are trying to solve classification problem. Again notoriously known example : classify handwritten digits (only 10 possible output - from 0 to 9).
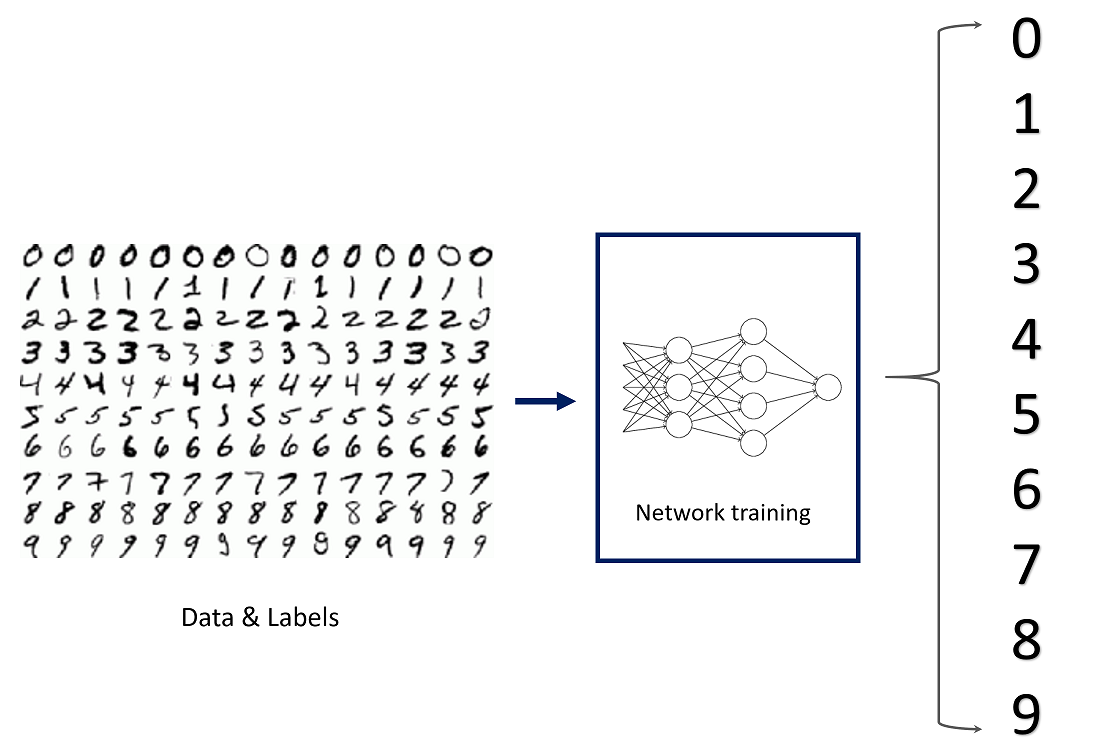
Link to video with solving this task using NN with beautiful visualization and easy-to-understand explanation (3Blue1Brown channel) : https://www.youtube.com/watch?v=aircAruvnKk
So far we had no idea about how to explain to model that prediction should be as close to real values as possible, but now we have strict mathematical representation of it - loss function. If it shows error, logically we should minimize this error in order to get better predictions. To minimize it we take derivative with respect to (w.r.t.) weights from function and equate it to zero :
df(x)/dk = d((prediction - true_value)^2)/dk = d(((x*k+b) - true_value)^2)/dk = 2*((x*k+b) - true_value)*x
The same for weight b :
df(x)/db = d((prediction - true_value)^2)/db = d(((x*k+b) - true_value)^2)/db = 2*((x*k+b) - true_value)
And when you update weights by subtracting original weights from their derivatives you decrease the error
I think that's enough for you to read. To encourage you to study further, i will tell you about what tasks are solved/can be solved with supervised learning :
1) Autonomous driving car
2) Predict dollar exchange rate
3) Face recognition
...
And many more. I hope, i could inspire you.