Data Scraping: How It Works and How to Run It Through a Proxy Pool
private proxiesData scraping on shops and catalogs needs many addresses at once: run website data scraping through a private IPv4 pool with unmetered traffic and a list that refreshes every 15 minutes.
Data scraping is the automatic collection of information from websites, apps or files into a structured form such as a table, a database or a JSON feed. A scraper requests a page, finds the fields it needs, like a price, a name or a rating, writes them down and moves on to the next page.
Ten pages go through from any connection. Ten thousand pages an hour from one server address run into the site limits: 429 codes, captcha pages and slow answers.
What is data scraping used for
Shops track competitor prices and stock. Brands watch how their products show up in marketplace search. Travel sites compare hotel rates by date, and analysts collect listings, reviews and job posts to see a market in numbers.
The output format depends on who reads it. Analysts take CSV or Excel, developers take JSON, and a running price tracker writes straight into a database table with a time stamp on every row.
Web scraping is the most common form of data scraping, and it is the form that needs proxies. Every request leaves from an IP address, and every site counts requests per address. Spreading them across a pool keeps the count on each address low while the job as a whole runs at full speed.
Data scraping tools and where the proxy list goes
Small jobs run on Python with requests or httpx and a parser such as BeautifulSoup or lxml. Large crawls use a framework like Scrapy, which handles queues, retries and export on its own. Desktop apps such as Octoparse let you pick fields with clicks and keep the proxy list in the task settings.
Each of them takes the same list. In code it is one parameter per request, in a desktop app it is a text field where you paste lines in IP:PORT format. WinGate access is bound to the IP of the machine that runs the scraper, so the lines carry no login and work in any tool as they are.
Website data scraping at scale
The sketch below collects pages in parallel through a pool with aiohttp and writes the status and size of each answer to a CSV file. It reads the list link from the dashboard, gives every request a random address and moves to another address after a failure.
import asyncio, csv, random
import aiohttp

LIST_URL = "your list link from the dashboard"
URLS = [f"https://shop.example.com/catalog?page={n}" for n in range(1, 2001)]

async def fetch(s, sem, pool, url):
    async with sem:
        for _ in range(3):
            proxy = "http://" + random.choice(pool)
            try:
                async with s.get(url, proxy=proxy, timeout=aiohttp.ClientTimeout(total=10)) as r:
                    body = await r.read()
                    if r.status == 200:
                        return url, r.status, len(body)
            except (aiohttp.ClientError, asyncio.TimeoutError):
                pass
            await asyncio.sleep(random.uniform(0.5, 1.5))
        return url, "fail", 0

async def main():
    async with aiohttp.ClientSession() as s:
        pool = (await (await s.get(LIST_URL)).text()).split()
        sem = asyncio.Semaphore(100)
        rows = await asyncio.gather(*(fetch(s, sem, pool, u) for u in URLS))
    with open("pages.csv", "w", newline="") as f:
        csv.writer(f).writerows(rows)

asyncio.run(main())
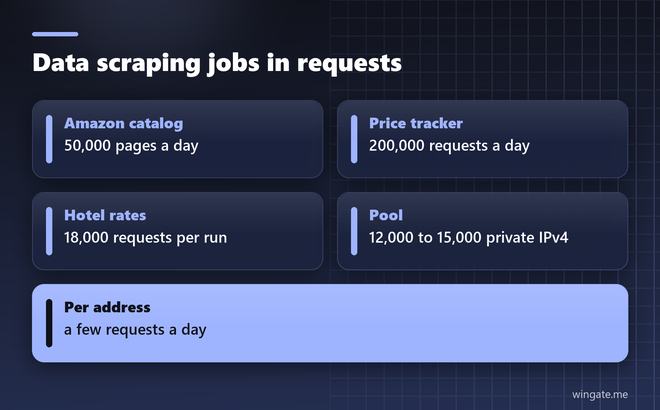
The semaphore value is the number of open connections, so keep it under the thread limit of your plan. With 100 parallel requests on a pool of 12,000 to 15,000 private IPv4, each address is used rarely, and a slow one holds back a single request at most.
Keep the load on each site reasonable and follow its robots.txt rules. Short timeouts, a retry through a different address and small random pauses do more for a steady run than a high thread count.
Amazon product data scraping by ASIN
Amazon product pages carry the title, price, rating, review count and seller offers, and the ASIN in the URL identifies each product. A catalog of 50,000 ASINs checked once a day means 50,000 page loads, and Amazon answers a high rate from one address with a 503 page or a captcha. A pool keeps that rate low: amazon product data scraping through 12,000 addresses comes to about four requests per address per day.
Product pages are heavy, with HTML that often runs to hundreds of kilobytes before any images. On a plan with unmetered traffic the page size has no effect on the price, so you can save the full HTML and parse new fields later without a second crawl.
Ecommerce data scraping for prices and stock
A price tracker for 5 competitors with 10,000 products each makes 50,000 requests per pass. Four passes a day come to 200,000 requests, or about 17 per address per day across 12,000 addresses. Stock checks can reuse the same pages, since price and stock usually sit on one product card.
Save the time of each reading next to the price. A report built on that column shows when a competitor changed a price to within a few hours, and how long a product stayed out of stock.
Hotel data scraping across dates
Hotel rates change with the check-in date, the length of stay and the number of guests, so one hotel turns into many requests. 200 hotels checked for the next 90 nights at a single length of stay come to 18,000 requests per run. Run it twice a day and a single address would carry 36,000 requests to the same few booking sites, which is a job for a pool.
Rates come back per date, so store the check-in date, the nights, the guests and the price in one row. A table built that way shows the cheapest dates for each hotel with a single sort.
Data scraping services or your own pool
Data scraping services hand over the finished table and charge per record or per request, which suits a one-off job. A job that runs every day costs less on your own scraper with a pool priced by threads. WinGate sells access to 12,000 to 15,000 private IPv4 online during the day from 3,000 to 5,000 networks, with HTTP, HTTPS and SOCKS5 on the same addresses, and the list comes as a link or a file.
Prices go by threads and term. Up to 1,000 threads cost $15 a day, $75 a week or $190 a month, and up to 3,000 threads cost $30, $180 or $600. The free test runs up to 2 hours on the 1,000 thread plan: point the scraper at your real targets at half your usual threads and watch the share of 200 responses. You pay in crypto, and access to the pool starts as soon as the payment goes through.