Choosing Between Web Push and In-Page Push Advertising Traffic
James CarterIf you have ever watched a push notification slide onto a screen, you already know how fast a decision gets made. A message appears, a title is read in a fraction of a second, and the thumb either moves or the notification disappears. Buying push traffic means buying a slice of that split-second attention, and the price you pay per click, the quality of the audience behind it, and the way the message renders on the device all determine whether the spend returns a profit. This guide walks through how push advertising actually works, where the two main formats differ, how to judge a source before you scale it, and how to launch a campaign that teaches you something useful within the first few days. The starting point is that you are not buying impressions in the way display banners work. You are buying a moment of permission-based or near-permission-based attention, and that distinction shapes almost every decision that follows.
FroggyAds publishes push starting bids from $0.003 per click, which is one of the lowest entry points in performance advertising, and it offers push, native, display and pop campaigns across 750+ SSP sources. A low entry bid makes it cheap to test, but it also means the number on the bid screen tells you very little about what a click will cost you once it converts. A $0.003 click that never reaches a landing page, or that lands on a slow page and bounces, is expensive at any price. Treat the starting bid as a door, not as a forecast. The rest of this guide explains how to check what is behind that door. A cheap bid alone does not settle whether a campaign is worth running, so it helps to judge push ads traffic by the conversions it produces rather than the price printed on the bid screen.
Understanding the Two Push Formats: Classic Web Push vs In-Page Push
Push advertising is not one thing. The term covers two distinct delivery formats that share a visual style but differ in how the audience is reached, what permission sits behind them and how the message is rendered. Confusing them leads to bad budgeting, misread results and, in some cases, claims about audience quality that cannot be supported. Before you choose a format, you need to know exactly what each one is doing on the user's device.
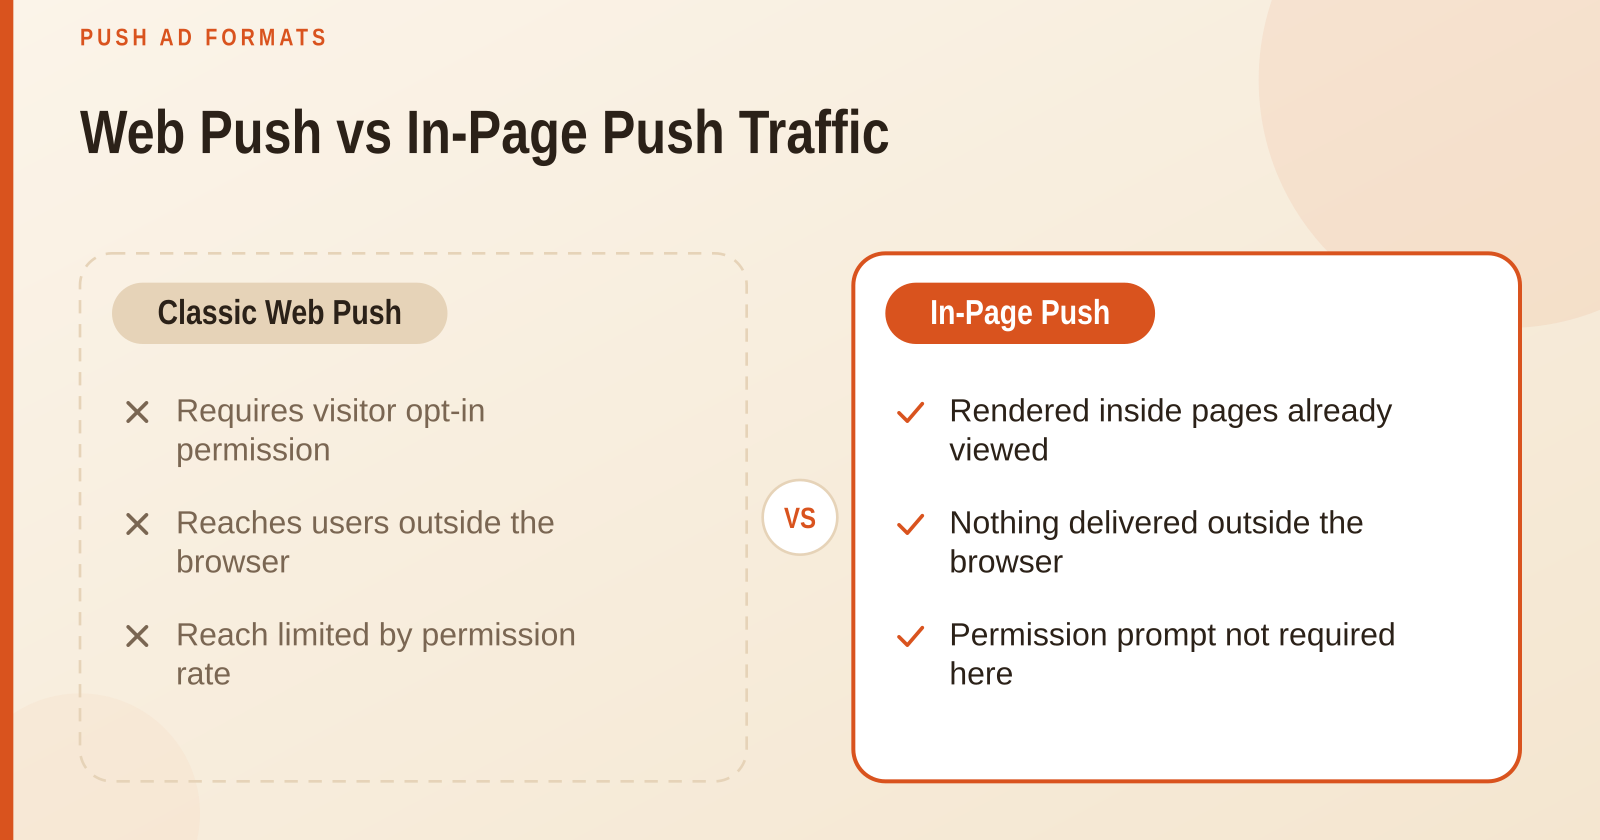
Classic web push depends on the browser's notification system. A visitor is shown a permission prompt by a site, and if they accept, that site can send notifications that appear outside the browser window, even when the tab is closed, subject to the browser and operating system permitting it. The W3C Push API describes how background messages reach a web application, and the WHATWG Notifications standard describes how notifications are displayed and how permission is requested and recorded. The practical consequence is that classic web push reaches people who have explicitly opted in to receive messages from a particular origin, which is why this inventory is often described as permission-based. It is also why reach is bounded by how many visitors accept the prompt in the first place.
In-page push works differently. The ad is rendered inside a web page the visitor is already viewing, using a layout that resembles a notification: a small card with an icon, a title and a short body. Nothing is delivered to the device outside the browser, and the visitor has not granted browser-notification permission to the advertiser. This matters for how you describe the audience and how you interpret the data. A click on an in-page unit is a click on a page element, and the visitor's relationship to the notification concept is purely visual. Mixing the two formats in one report, then drawing conclusions about "subscribers," produces a picture that does not correspond to what actually happened.
Where in-page inventory fits in a mixed campaign is a question of volume and context. Because it does not depend on prior opt-in, it can scale to a wider pool of page views, though the attention it earns is shaped by the surrounding page. Classic web push offers a more direct line to a visitor who has shown interest in notifications, but the pool is smaller and grows only as the publisher collects permissions. A sensible approach is to run the two as separate cells, each with its own budget, its own creative variants and its own acceptance rule, and to compare them on validated outcomes rather than on click-through rates that were produced under different conditions.
Key Differences in Permission, Delivery and Rendering
Permission is the first and most consequential difference. Classic web push requires the visitor to accept a browser prompt, and the browser records that choice. Revoking permission later removes the channel entirely. In-page push requires no such permission, which means its reach is not gated by an opt-in rate. These two facts explain why audience size is more stable for in-page inventory and why classic web push can show sharper swings when a publisher's permission prompt is changed or a browser updates its rules. If your forecast assumes a steady daily volume, check which permission model underpins the source you are buying.
Delivery timing and fatigue follow from the permission model. Classic web push arrives at the device regardless of what the visitor is doing, which means a poorly timed message can feel intrusive and drive opt-outs. Frequency caps matter here, because a subscriber who receives the same offer three times in a day is likely to revoke permission or ignore the next message. In-page push is shown only while the visitor is on the page, so fatigue presents differently: the same unit can appear repeatedly to one person across a session, and the signs of this are a falling click rate within the same visitor's session rather than a spike in opt-outs. Each format needs its own cap and its own fatigue watch.
Rendering is the third difference, and it is the one that most often surprises new buyers. The title and body you write may be truncated differently on a phone than on a desktop, and an icon that looks sharp in one operating system can be blurred or cropped in another. Notification systems impose their own display rules, and in-page units impose the layout of the host page. A title that reads clearly in a preview can lose its key qualifier once the operating system truncates it. The practical discipline is to preview the message at the sizes it will actually be shown, on the devices you are targeting, and to avoid putting the decisive word at the end of a long title where it is the first thing to be cut.
A notification has the length of a sentence and the lifespan of a glance. If the reason to click is not visible in that glance, the campaign is asking the visitor to do the work of reading the rest of the offer somewhere else.
How to Choose a Push Traffic Source: Criteria That Matter
Choosing a source is where most of the money is either protected or lost. Push sources differ in how they acquire subscribers, how they filter invalid clicks and how much detail they expose about where each click came from. The criteria below are the ones that separate a source you can scale from one you should abandon after the first week. None of them requires a special tool to assess; they require asking the right questions and reading the breakdowns carefully.
Start with subscriber sourcing for classic web push. Ask how the publisher collects permissions, whether the prompt is shown on a relevant page after genuine engagement or immediately on arrival, and whether there is any incentive that inflates opt-ins without interest behind them. A permission rate that jumps sharply overnight, or an audience whose geographic mix changes without explanation, is a signal worth investigating before money goes in. For in-page inventory, the equivalent question is which pages the units run on and whether those pages attract the audience you actually want to reach.
Fraud signals are visible in the data if you know where to look. An abnormal click-through rate spike, particularly one that arrives at an unusual hour and lacks any matching rise in time on site, suggests automated clicking. Clicks that arrive at perfectly regular intervals, or in bursts that do not match human browsing, are another warning. The most telling sign is a cluster of clicks with zero conversions and near-zero post-click engagement, because a real audience rarely behaves that uniformly. You do not need to diagnose every anomaly; you need to notice when a source's numbers look too clean to be human and stop the spend until you understand why.
Geo, device and browser breakdowns are a required check before scaling. A campaign that looks profitable in aggregate can be carried by one country or one browser while the rest of the traffic loses money. Split the results by these dimensions early, and cut any segment whose post-click cost is well above your target even if its click-through rate is attractive. Looking at a source's average performance hides the segments that are quietly draining the budget, and those are usually the ones that need to be found first.
Pricing Models and CPC Floors
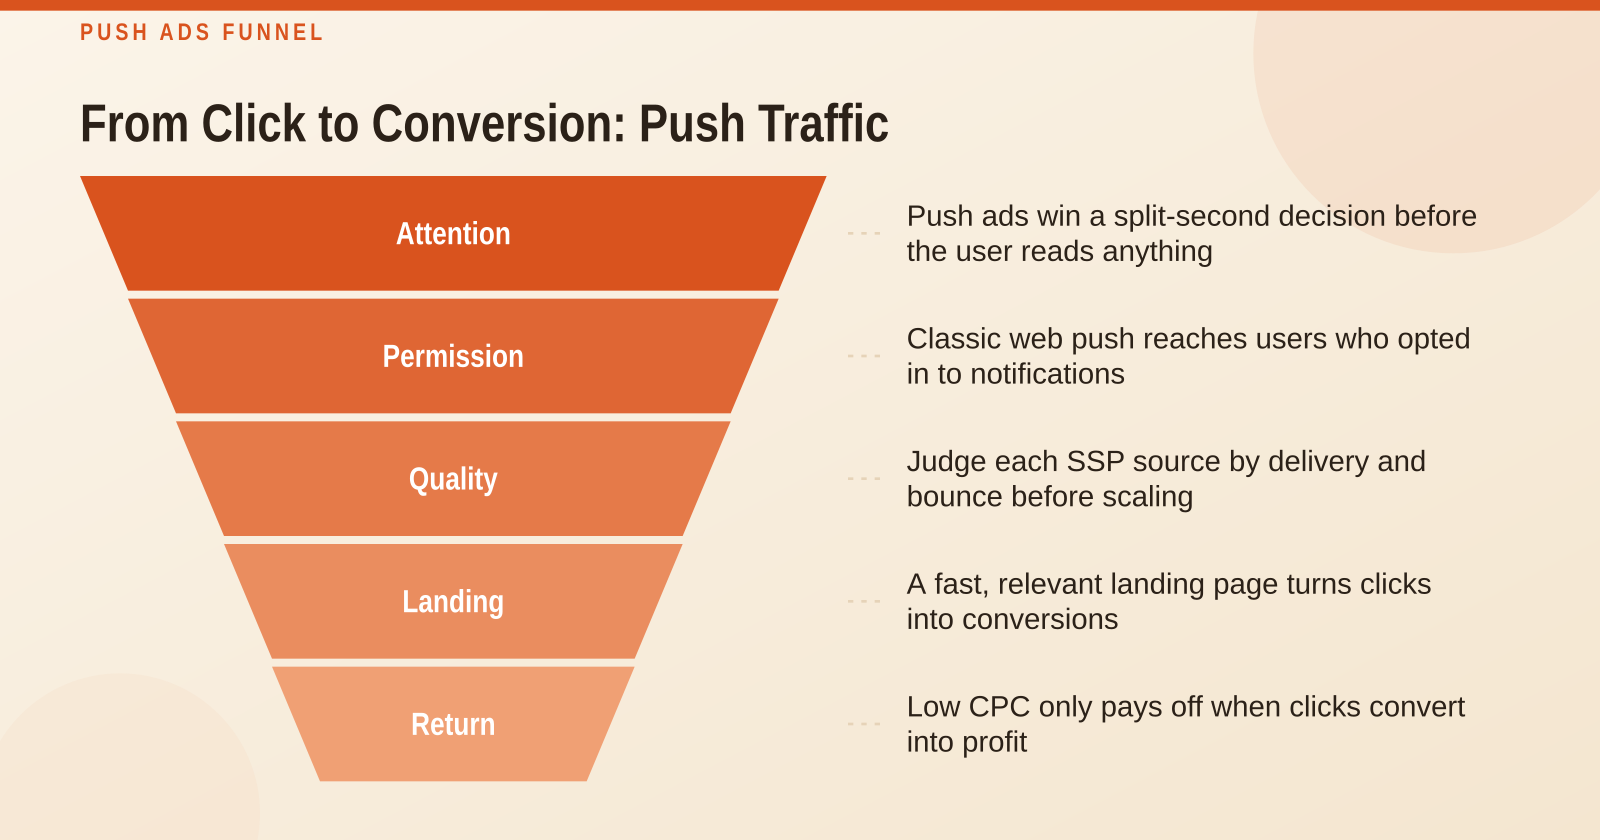
Push is usually bought on a cost-per-click basis, and the attraction of a low floor is obvious. A starting CPC of $0.003 lets you spend small amounts to learn how messages and sources behave. The catch is that cost per click tells you what you paid for the visit, not what you paid for the outcome you actually want. To understand true cost, you need to follow each click to the next stage that matters to your offer, whether that is a landing page view, a lead, a sign-up or an approved sale, and divide your spend by the number of those outcomes.
Bid strategy follows from that calculation. Once you know the post-click cost of an acceptable outcome, you can work backward to the maximum CPC that still leaves room for margin. Raise a bid when a source produces outcomes below your target and has room to scale; lower it, or pause, when the cost of an outcome drifts above target for several days. The right adjustment is usually modest and made in steps, because large sudden changes reset the delivery of the campaign and make results harder to read. The important habit is to decide the threshold before launch so that you are not tempted to keep spending because a campaign looks busy.
Hidden costs erode a low CPC quickly. A minimum deposit requirement ties up capital before you have proven anything, and creative approval delays can cost days of the testing window you planned around. Cap restrictions limit how much a given source can deliver, which can make a promising source too small to matter. There is also the cost of your own time spent on messages that never ran because of a rejected headline. Factor these into your planning as real costs, and budget for a test that can survive a few days of approval friction rather than assuming every unit goes live on the first attempt.
A practical way to size the first test is to decide in advance how many outcomes you need to learn anything useful, then work out the spend required to produce them at your expected post-click cost. If you need thirty leads to judge a message and your expected cost per lead is well above the cost per click, the budget must reflect that gap, not the attractive headline price. Many buyers abandon good campaigns because they stopped before the sample was large enough to separate signal from noise, and many others keep spending on weak ones because they never set a stopping rule. Writing both rules down before the first click is the cheapest protection you can buy.
Vendor Transparency and Reporting Depth
Reporting depth separates a platform you can learn from and one you can only gamble on. At minimum, you should be able to see performance at the level of source, campaign, creative and placement, with clicks, costs and the outcomes your tracking records. If a platform only shows totals, you cannot tell which message or source is responsible for a result, and you cannot make a keep, block or retest decision with confidence. FroggyAds offers campaign reporting and source-level results in its self-serve dashboard, which is the level of detail a buyer needs to act on the data rather than guess.
Postback and tracking integration are the foundation of that reporting. A postback is a server-to-server signal that tells your system a conversion has occurred and carries the identifiers needed to link it back to the original click. Without a working postback or equivalent tracking, conversions happen in a place your reports cannot see, and optimisation is blind. Check that the click identifiers survive the path from the ad to your landing page and on to the conversion event, and test the chain end to end with a real click before scaling any spend. A broken identifier at any point produces conversions that cannot be attributed, which is one of the most common and most expensive mistakes in paid traffic.
Support responsiveness is a selection factor that is easy to underrate until something breaks. When a creative is rejected, a campaign stops delivering or a tracking link returns an error, the speed and clarity of the reply determines how many days of budget are wasted. Ask in advance how issues are raised and what response you can reasonably expect, and note how the platform handled the first problem you encounter during testing. That early experience is a fair preview of what you will face when a campaign is performing and the stakes are higher. Before committing a budget, it is worth checking how a push traffic provider handles rejected creatives and tracking errors, because those details decide how quickly a stalled campaign gets fixed.
Step-by-Step: Launching a Push Campaign from Setup to First Results
A push campaign succeeds or fails largely before the first click, in the decisions made about the offer, the landing page and the tracking. Start by choosing an offer that suits a short, direct message. Push works best when the benefit can be stated in a few words without relying on the reader to understand a complicated product, and when the offer is one the visitor can evaluate on the spot. Verticals that depend on long explanations or heavy qualification tend to struggle, not because push is ineffective but because the message cannot carry enough of the decision.
The landing page must match the message closely. If the notification promises a specific benefit, the destination should confirm that benefit within the first screen, load quickly on the device you are targeting and present a clear next step. A mismatch between the headline and the page is one of the fastest ways to lose a click that already cost you money. Before launch, open the destination on a phone and on a desktop, time how long it takes to become usable, and check that every link you intend to send traffic to works. Then confirm that the tracking parameters are present and that the conversion event fires.
Creative writing comes next, and it is shaped by the rendering limits discussed earlier. Put the most important word, the benefit or the offer name, at the start of the title, because truncation will remove the end first. Use the body to add one concrete detail or a single clear action, not to repeat the title. Choose an icon that remains recognisable at small size, and use an image only where the selected format supports it and the image adds information rather than decoration. Write two or three variants that differ in one meaningful way, such as the benefit stated or the reason given, so that a result can be attributed to a specific difference.
Testing structure keeps the results readable. Hold the destination and the core targeting constant while you test messages, and track each creative separately so that a result maps to a single version. Two or three variants are usually enough for an early test; more than that splits the budget so thinly that no version reaches a useful sample. Decide in advance how long each variant will run and what sample size will be required before you draw a conclusion, and resist the temptation to declare a winner after a few hours of data.
Launch, Budget Control and the First 72 Hours
The first seventy-two hours are about learning, not about profit. Set an initial cap that is large enough to produce a readable sample from your best-guess source and small enough that a bad source cannot consume your budget before you notice. Monitoring should be frequent in the first day: check that the campaign is delivering, that clicks are reaching the landing page, that tracking records conversions, and that no segment is absorbing a disproportionate share of spend. Hourly checks are sensible for delivery and tracking health; daily checks are more appropriate for performance, because individual hours are too noisy to judge cost.
Typical timelines depend on volume and on the outcome you are measuring. A campaign aimed at clicks can show a clear pattern within a day, while one aimed at approved sales or retained sign-ups may need several days because the outcome arrives late. Allow for postback delays and for affiliate or advertiser approval windows, since a conversion that is recorded today may not be confirmed for a while. Judging a message on a window that closes before the outcomes arrive is one of the most common ways to kill a good test.
Budget control during this period is about discipline. Increase spend on a source only when its cost of acceptable outcomes is below target and the sample is large enough that a single lucky day is unlikely to explain it. Pause segments that are clearly losing money after a fair sample, and note the reason in your log so the decision can be reviewed later. The aim of the first three days is to find out which sources, messages and segments deserve more budget, and to have a written record of why.
The most expensive push campaigns are rarely the ones that failed loudly. They are the ones that kept running quietly for a month because nobody wrote down what success looked like on day one.
Common Mistakes in Push Campaigns and How to Avoid Them
Frequency is the first mistake that undermines a push campaign over time. A subscriber or visitor who sees the same offer repeatedly becomes less likely to click and, in classic web push, more likely to revoke permission entirely. The signs are a falling click-through rate for the same audience, a rising share of clicks from a single cohort and an increase in opt-outs where that data is visible. Set a frequency cap from the start, and treat a steady decline in response as a reason to rotate creative or reduce delivery rather than as a reason to raise the bid.
Ignoring geo and device splits is a closely related error. A campaign can look healthy in total while one country, one operating system or one browser generates the majority of the cost and almost none of the outcomes. Checking these breakdowns regularly is the only way to see the losing segments, and cutting them often improves the result more than any change to the creative. Scaling too fast after an early spike is the other side of the same problem: a strong first day is frequently a short-term effect of novelty, and budget increased sharply on that basis tends to return to average or below.
Creative and offer mismatches cause a large share of wasted spend. A headline that promises something the landing page does not deliver produces clicks that leave within seconds, which both wastes money and damages the source's apparent quality. Misleading wording can also create complaints and refund requests that follow the campaign for weeks. Rotate creative before performance decays, but do not confuse rotation with reinventing the offer; each variant should be honest about the same underlying benefit so that the test measures how the message is written, not whether the advertiser is trustworthy.
Measurement mistakes are the most damaging because they corrupt every later decision. Judging a campaign on click-through rate alone rewards curiosity rather than intent, and it can make a message that attracts clicks from the wrong people look like a winner. Misreading attribution windows, or forgetting that postbacks arrive late, makes a healthy campaign look weak in the first days and a weak one look fine. Optimising on too small a sample turns random variation into apparent insight. The fix is the same in each case: decide the outcome that matters, the window in which it will be counted and the sample size needed before acting.
What Tasks the FroggyAds Platform Solves for Advertisers
FroggyAds is a self-serve DSP, meaning an advertiser can launch and manage campaigns directly rather than through an account manager. Within one buying interface, advertisers can access classic web push and in-page push inventory, with the two formats kept distinct so that each can be budgeted, tested and reported on its own terms. That separation matches the permission, delivery and rendering differences described above, and it helps avoid the mistake of treating two different audiences as one. The platform also draws on 750+ SSP sources, so a campaign can be spread across a wide supply base rather than depending on a single publisher.
Bidding is handled through CPC, with push starting bids published from $0.003 per click. SmartCPC bidding works alongside this to adjust delivery toward the traffic that is most likely to perform, which makes low-cost testing more practical while keeping control with the advertiser. Adscore is the platform's traffic-quality measure, and it is worth reading it as one input among several rather than as a guarantee: use it to prioritise which sources to examine first, then apply your own checks on geo, device, browser and post-click results. Traffic-quality controls of this kind reduce the amount of invalid spend a buyer has to clean up after the fact, but they do not replace the need to judge outcomes.
For the day-to-day work of running a campaign, the dashboard provides targeting by geo, device and browser, along with reporting that shows results by source identifier and campaign. This is the level of detail needed to make the keep, block or retest decisions described throughout this guide. A buyer who wants to find the segments losing money, the sources producing acceptable outcomes and the creative behind each result can do so without leaving the platform, and can then move budget toward what the data supports.
A campaign that begins with a clear offer, a matching landing page, verified tracking and a written stopping rule is far more likely to produce something you can trust. Push rewards advertisers who respect its short format and its specific audiences, and it punishes those who treat a notification as a miniature banner or who judge success by the click alone. Start with a small, well-instrumented test in whichever format fits your offer, read the results by source, device and outcome rather than in aggregate, and scale only what your own evidence supports. Done that way, a $0.003 starting bid becomes a controlled experiment with a clear answer, and the answer tells you where your next dollar should go.