2026 Anthropic CCAR-P–Professional Latest Test Cram
Dumpkiller is driven by the ambition of making you succeed. Our Anthropic CCAR-P study material offers you high-quality training material and helps you have a good knowledge of the CCAR-P actual test. The team members of Dumpkiller work with a passion to guarantee your success and make you prosperous. We provide the CCAR-P Test Engine with self-assessment features for enhanced progress.
Anthropic CCAR-P Exam Syllabus Topics:
Section Weight Objectives Topic 1: Solution Design & Architecture 17% - Multi-agent systems and orchestration
- Decomposition techniques for complex problem solving
- Architectural patterns
- 1. Augmented LLM architectures
- 2. Workflow architectures
- 3. Agentic architectures
- End-to-end architecture design
- Translating business problems into Claude-based AI solutions
- Alignment with business value, cost, performance, and SLAs
Topic 2: Evaluation, Testing & Optimization 16% - Production monitoring and optimization
- System issue diagnosis
- A/B testing
- Evaluation framework design
- Cost and performance optimization
- Evaluation metrics and datasets
Topic 3: Stakeholder Communication & Lifecycle Management 14% - Service-level agreements
- Solution lifecycle management
- Discovery and requirements gathering
- Architecture documentation
- Stakeholder management
- Communicating architectural decisions
Topic 4: Integration 19% - RAG pipeline design
- 1. Retrieval
- 2. Indexing
- 3. Chunking
- Enterprise system integration
- Authentication and authorization analysis
- Claude integration mechanisms
- 1. API and CLI
- 2. Agent-to-agent integration
- 3. MCP
Topic 5: Developer Productivity & Operational Enablement 7% - Claude tooling configuration for teams
- AI-assisted developer workflows
- Debugging and operational issue resolution
- Developer enablement
Topic 6: Claude Models, Prompting & Context Engineering 13% - Guardrails
- Claude model selection and trade-offs
- Prompt reuse and context engineering strategies
- Context window optimization
- System prompts and prompt templates
Topic 7: Governance, Safety & Risk Management 14% - AI safety and guardrails
- Regulatory and compliance requirements
- Security and risk management
- Human-in-the-loop validation
- Ethical AI considerations
CCAR-P Latest Exam - CCAR-P Mock Exams
Do you want to double your salary in a short time? Yes, it is not a dream. Our CCAR-P latest study guide can help you. IT field is becoming competitive; a Anthropic certification can help you do that. If you get a certification with our CCAR-P latest study guide, maybe your career will change. A useful certification will bring you much outstanding advantage when you apply for any jobs about Anthropic company or products. Just only dozens of money on CCAR-P Latest Study Guide will assist you 100% pass exam and 24-hours worm aid service.
Anthropic Claude Certified Architect - Professional Sample Questions (Q10-Q15):
NEW QUESTION # 10
You are identifying signals that a deployment should re-enter design rather than continue iterating in place.
Which signal most directly indicates the need for a new design cycle?
- A. A minor copy edit is requested in a customer-facing string within the existing UI, which can be handled as a localized content change without altering component responsibilities or contracts.
- B. The system's current architecture cannot meet the new requirements without changes to component responsibilities or core contracts.
- C. A dashboard alert threshold needs a small numerical adjustment to reduce false-positive noise, which can be handled as an operational configuration change without a new design cycle.
- D. A runbook step requires a clarification edit to improve on-call guidance accuracy, which can be handled as a documentation update without changes to component responsibilities or core contracts.
Answer: B
NEW QUESTION # 11
You are supporting a team whose Claude Code sessions consistently load 60 or more MCP tools from many servers, exhausting context budget before the session begins.
Which adjustment most directly addresses this issue without removing capability?
- A. Enable Tool Search so tool definitions are deferred and discovered on demand rather than loaded into context upfront.
- B. Add additional MCP servers to give the team more capability, which increases rather than reduces the number of tool definitions loaded into the session's context budget.
- C. Increase the prompt's verbosity with additional instructions and context, which consumes more of the context budget rather than reducing the tool-definition overhead causing the issue.
- D. Disable every MCP server in the configuration to free up context budget, accepting that the team loses all tool access and cannot perform any MCP-dependent task in the session.
Answer: A
Explanation:
Tool Search applies progressive discovery to a large tool catalog. Instead of inserting every MCP tool's complete JSON schema and description into the initial context, Claude receives limited discovery information and loads the full definitions only when a task requires them. This preserves the available context for instructions, repository content, conversation history, and tool results without removing the underlying capabilities.
Anthropic's Claude Code documentation states that Tool Search keeps MCP context usage low by deferring tool definitions until Claude needs them. Only the tools actually selected enter the working context. Claude Code MCP Tool Search Anthropic's advanced-tool-use guidance also describes conventional multi-server configurations consuming tens of thousands of tokens before work begins, while on-demand discovery substantially reduces that overhead. Advanced Tool Use Option B solves context pressure by destroying required functionality. Option C worsens the constraint by adding more prompt tokens. Option D expands the exact source of context bloat.
The team should also improve server and tool descriptions so discovery returns the correct tools, monitor tool- selection quality, and keep frequently required foundational tools non-deferred only when evaluations justify the additional context cost.
Study Guide references/topics: MCP scaling; Tool Search; progressive discovery; deferred schemas; context- budget management; tool-selection accuracy.
NEW QUESTION # 12
A Claude architect at a health services organization is defining evaluation metrics for a clinical-summary pipeline. The pipeline must remain within a per-query cost ceiling and must never surface patient data to unauthorized roles.
Which two metrics directly address these requirements? (Select two.)
- A. BLEU score computed against a human-annotated reference summary set
- B. Per-query token cost measured against the defined cost ceiling
- C. Response latency at the 95th percentile across a one-week sample window
- D. Throughput measured as successful requests processed per minute
- E. Role-based access-control enforcement rate measured on a red-team dataset
Answer: B,E
Explanation:
The evaluation metrics must map directly to the two stated requirements. Role-based access-control enforcement rate, tested against a red-team dataset, measures whether requests from unauthorized identities, roles, or access paths are consistently denied. It converts the privacy and authorization requirement into an observable security metric and exposes bypass conditions that ordinary functional tests may miss. Because the requirement says patient data must never reach unauthorized roles, the acceptance threshold should be effectively 100% enforcement across representative and adversarial cases.
Per-query token cost directly measures compliance with the financial constraint. The metric should include uncached input, cache reads and writes where applicable, output tokens, thinking tokens, and any other billable components attributed to the request. Results can then be compared with the defined ceiling across normal, boundary, and worst-case inputs.
Anthropic's evaluation guidance identifies privacy preservation and price as distinct success criteria and emphasizes that criteria must be specific, measurable, and relevant to the application. Define Success Criteria and Build Evaluations BLEU may assess textual similarity but does not test authorization or cost. Throughput and percentile latency are valuable operational metrics, yet neither directly answers the two requirements in the scenario.
Study Guide references/topics: Multidimensional evaluation; privacy preservation; authorization testing; red- team datasets; token-cost measurement; requirement-to-metric traceability.
NEW QUESTION # 13
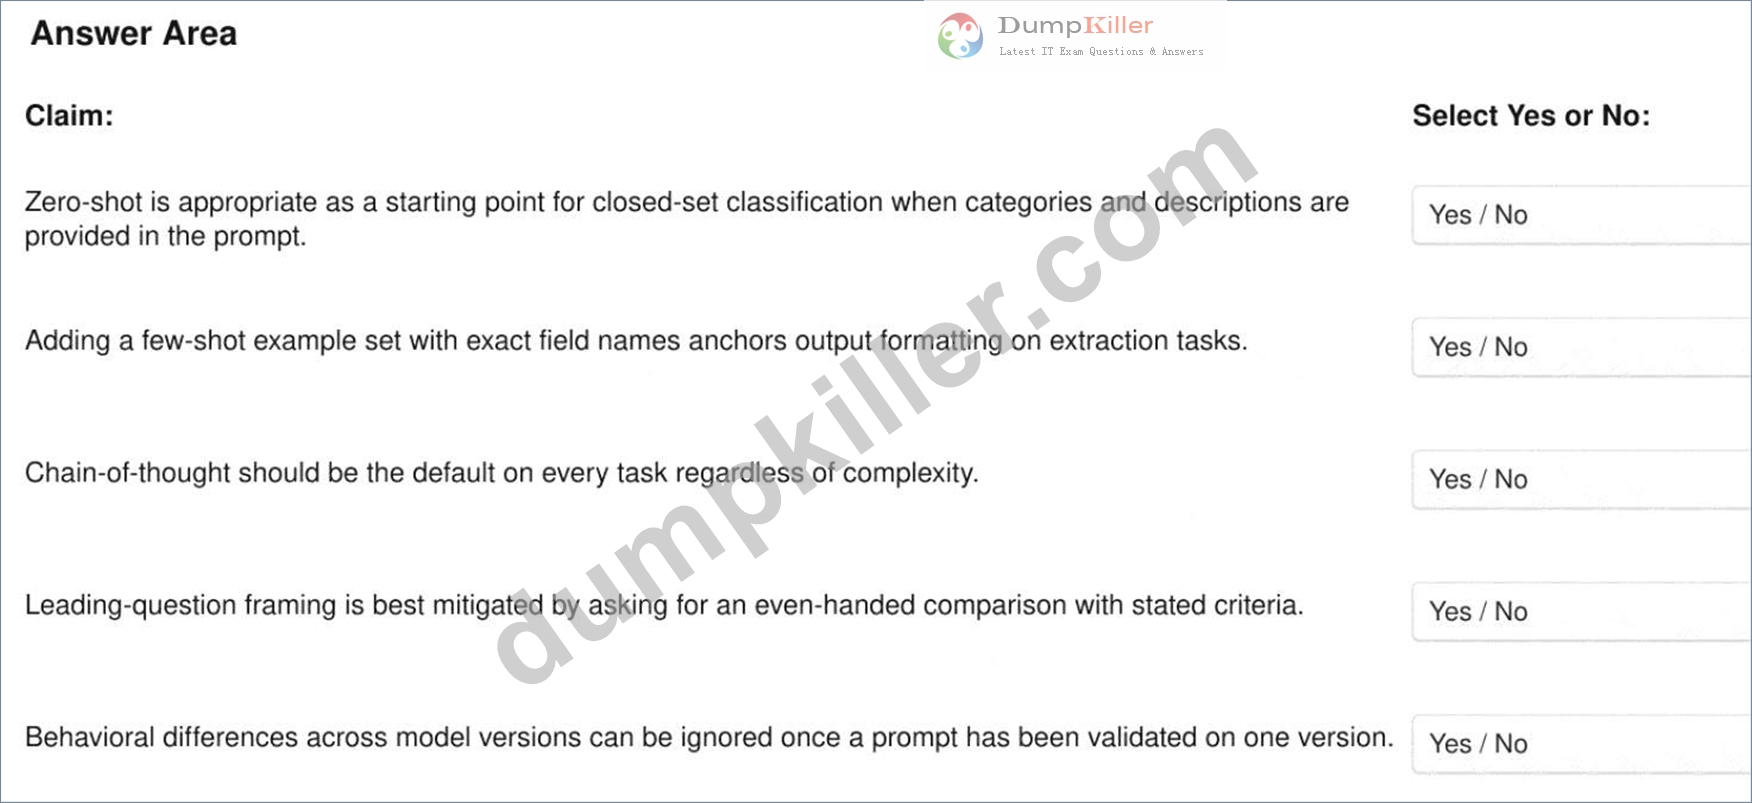
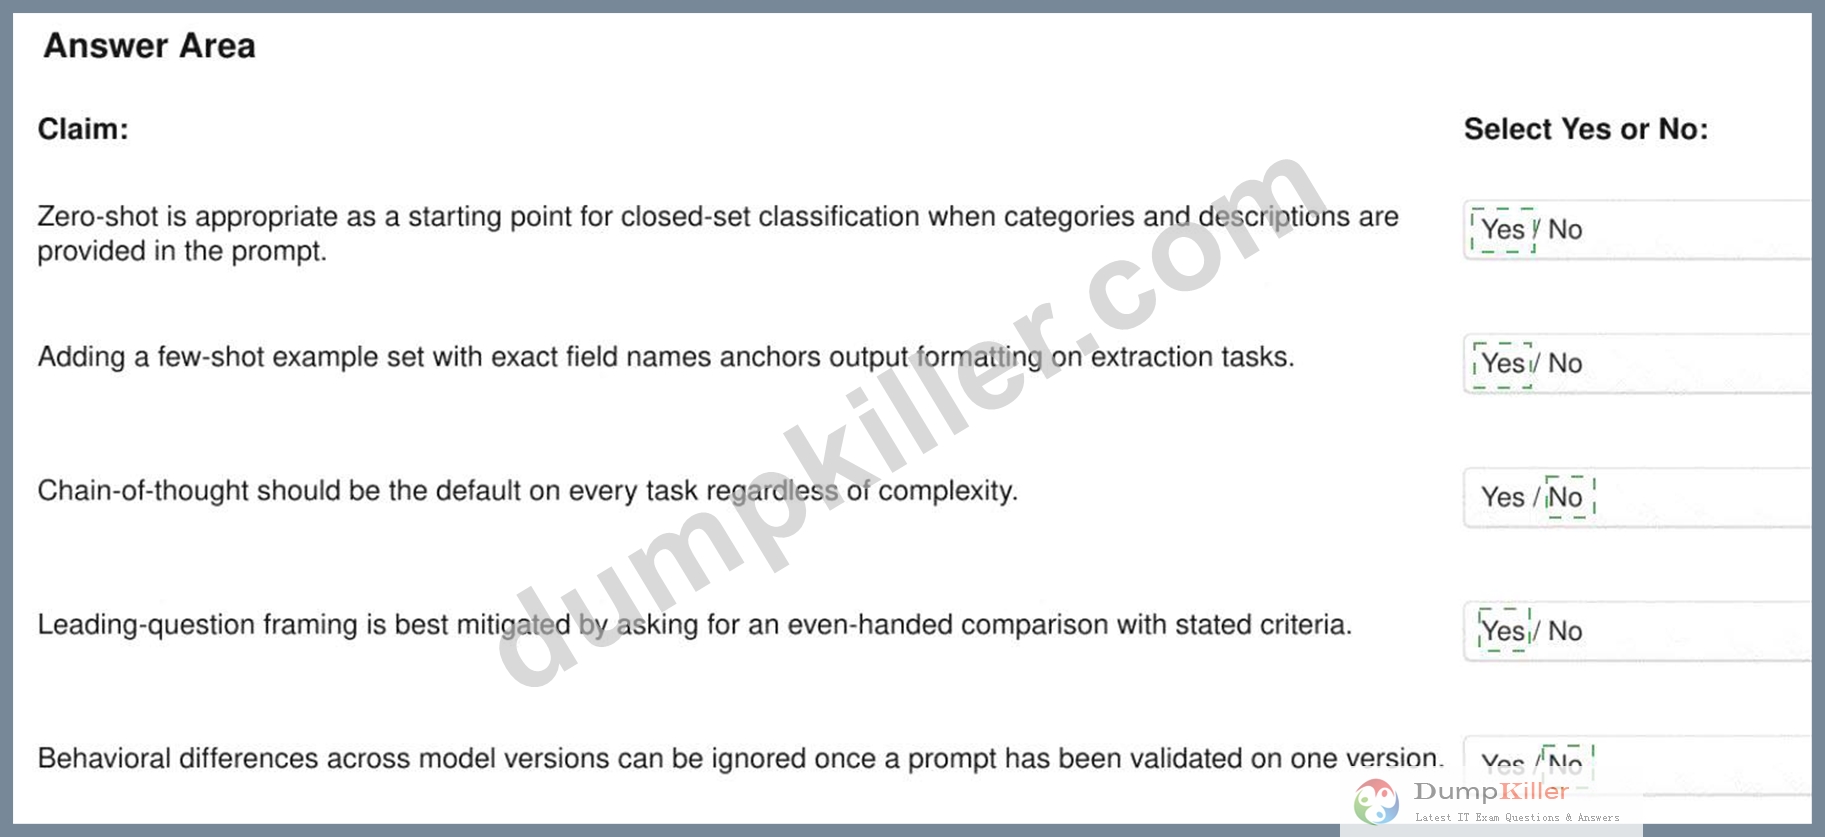
You are evaluating prompting claims in a peer's design document.
For each claim, select yes if the claim reflects sound practice. Otherwise, select no.
Answer:
Explanation:
Explanation:
Yes, Yes, No, Yes, No
Zero-shot prompting is a reasonable baseline for a clearly defined closed-set classifier because the model receives both the permissible labels and their meanings. Performance should then be measured against an evaluation set before additional prompt complexity is introduced. Few-shot examples are also sound for extraction because examples containing the exact field names demonstrate the required schema and reduce formatting ambiguity. Anthropic identifies examples as one of the most reliable methods for steering output format, structure, and consistency. Prompting Best Practices Chain-of-thought is not an unconditional default. Additional reasoning is appropriate when the task requires substantive decomposition or complex judgment, but routine classification and extraction may gain little while consuming more tokens and increasing latency. The technique should be selected according to evaluated task requirements.
An even-handed comparison governed by explicit criteria mitigates leading-question bias by requiring symmetrical treatment of alternatives rather than presupposing a preferred conclusion. Finally, prompt validation is model-specific. New model versions may follow instructions differently, change formatting behavior, alter tool selection, or produce different latency and cost characteristics. Anthropic's migration guidance consequently recommends reevaluating prompts and workloads against the new baseline. Model Migration Guide Study Guide references/topics: Zero-shot prompting; few-shot examples; reasoning techniques; neutral framing; model migration and regression evaluation.
NEW QUESTION # 14
The platform team at Trenova Systems, Inc. needs to reduce per-query cost and p95 latency for a high-volume Claude pipeline without degrading output quality on the core use case.
Which two optimizations directly target both cost and latency simultaneously? (Select two.)
- A. Expand the system prompt to include additional few-shot examples on every request.
- B. Increase max_tokens to reduce the frequency of truncated responses requiring follow-up calls.
- C. Add a retrieval step that fetches the full source corpus into the context window before generation.
- D. Route straightforward query types to a smaller, faster Claude model and reserve the full model for complex cases.
- E. Enable prompt caching on the static system-prompt prefix to reduce billable input tokens on repeated calls.
Answer: D,E
Explanation:
Prompt caching reduces repeated input processing when a stable system prefix is reused, directly lowering input cost and processing latency. Model routing provides the second optimization: routine cases can use a faster, lower-cost model, while difficult cases retain access to the more capable model. The routing policy must be validated against representative evaluations to confirm that quality remains within the required threshold. Increasing max_tokens can increase output cost and generation time. Retrieving the complete corpus and adding examples to every request both enlarge the input, worsening latency and token consumption. Anthropic identifies prompt caching as a cost-and-latency optimization and recommends selecting a model according to the workload's quality, speed, and economic requirements. Prompt caching ; reducing latency
NEW QUESTION # 15
......
Do you want to pass your exam buying using the least time? If you do, you can choose us, we have confidence help you pass your exam just one time. CCAR-P training materials are edited by skilled professionals, they are familiar with the dynamics for the exam center, therefore you can know the dynamics of the exam timely. Besides, we offer you free demo for you to have a try before buying CCAR-P Test Dumps, so that you can have a deeper understanding of what you are going to buy. Free update for one year is available, and you can obtain the latest version if you choose us, and the update version for CCAR-P exam materials will be sent to your email address automatically.
CCAR-P Latest Exam: https://www.dumpkiller.com/CCAR-P_braindumps.html
- Free PDF 2026 First-grade Anthropic CCAR-P: Claude Certified Architect - Professional Latest Test Cram 🖌 Go to website ➤ www.troytecdumps.com ⮘ open and search for 「 CCAR-P 」 to download for free 🤳Certification CCAR-P Dump
- 100% Pass Quiz Anthropic - Newest CCAR-P - Claude Certified Architect - Professional Latest Test Cram 🏪 Download { CCAR-P } for free by simply searching on 《 www.pdfvce.com 》 🔌Test CCAR-P Lab Questions
- CCAR-P Reliable Exam Prep 🦊 CCAR-P Answers Free 🦙 CCAR-P Reliable Exam Prep 🚰 Go to website ➽ www.troytecdumps.com 🢪 open and search for ➽ CCAR-P 🢪 to download for free 🥌CCAR-P Vce File
- Using CCAR-P Latest Test Cram - Get Rid Of Claude Certified Architect - Professional 💚 Enter ☀ www.pdfvce.com ️☀️ and search for ➥ CCAR-P 🡄 to download for free ↗Test CCAR-P Lab Questions
- Anthropic CCAR-P Dumps | Questions (2026) 🔟 Go to website ➠ www.verifieddumps.com 🠰 open and search for ➠ CCAR-P 🠰 to download for free ⏮CCAR-P Fresh Dumps
- Anthropic CCAR-P Dumps | Questions (2026) 🤵 Copy URL ⏩ www.pdfvce.com ⏪ open and search for [ CCAR-P ] to download for free 🔲CCAR-P Actual Exam Dumps
- 2026 Latest Anthropic CCAR-P: Claude Certified Architect - Professional Latest Test Cram ☝ Open website ☀ www.practicevce.com ️☀️ and search for { CCAR-P } for free download 🧝CCAR-P Actual Exam Dumps
- CCAR-P Exam Sample Questions 🟦 CCAR-P Vce File 🈵 CCAR-P Certification Materials 🍒 Easily obtain ▛ CCAR-P ▟ for free download through ( www.pdfvce.com ) 💬CCAR-P Fresh Dumps
- CCAR-P practice materials - CCAR-P real test - CCAR-P test prep ↩ Search for ▶ CCAR-P ◀ and obtain a free download on ▷ www.examcollectionpass.com ◁ 🧟Certification CCAR-P Dump
- Using CCAR-P Latest Test Cram - Get Rid Of Claude Certified Architect - Professional ✉ Search on ⇛ www.pdfvce.com ⇚ for 【 CCAR-P 】 to obtain exam materials for free download 📦CCAR-P Certification Materials
- CCAR-P Actual Dump 🥟 Test CCAR-P Dumps Free 📪 Pass CCAR-P Test 💦 Enter ➡ www.dumpsmaterials.com ️⬅️ and search for [ CCAR-P ] to download for free 📩CCAR-P Visual Cert Test
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, vrcmods.com, annualeventpost.com, vrcmods.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes